
Youchuan V8.1 Text-to-Image
Youchuan V8.1 generates four images from a text prompt, with optional native 2K HD, a style reference, and aspect-ratio / stylize / chaos / weird controls.
What it does
Youchuan V8.1 Text-to-Image, in practice.
> About Youchuan (悠船): "Youchuan V8.1" is Midjourney's V8.1 model delivered through Youchuan (悠船), Midjourney's officially authorized platform in China — self-branded *"Midjourney 中国实验室" (Midjourney China Lab)* and operated by Xiaochuan Creative (Shanghai) Network Technology Co., Ltd. (小船创意). Youchuan is a legitimate, licensed distributor of Midjourney's models (not a third-party clone): it offers the same Midjourney technology, localized for the Chinese market with priority access to new model versions. Youchuan V8.1 is the latest iteration of Midjourney's image-synthesis model. This README covers the two core generation endpoints: It belongs to a larger Youchuan V8.1 family on this platfor
- Native 2K HD output without a separate upscaler: V8.1 generates directly at 2048px resolution, eliminating the dedicated upscaling step required by earlier versions. HD renders take roughly 1.33 GPU-minutes and standard-definition renders under 1 GPU-minute, with HD running approximately 3× faster and cheaper than in V8.
- ~4–5× faster generation: The GPU-native PyTorch rewrite delivers an estimated four-to-fivefold speedup in generation time over previous Midjourney versions (a Midjourney-stated figure, not an independent benchmark), improving iteration speed for creative workflows.
- Improved text rendering: V8.1 renders in-image text more reliably, with quoted strings in prompts used to specify the intended text — narrowing a long-standing weakness relative to text-specialized competitors.
- Stronger prompt-following: The model adheres more closely to prompt instructions, improving controllability and reducing the prompt-engineering effort needed to achieve a target composition.
- Restored image conditioning: Image prompts and image weights — absent in the V8.0 alpha — returned in V8.1, alongside backward compatibility with V7 style references (srefs), moodboards, and personalization profiles. (Image-driven generation is offered here as the dedicated `youchuan/v8.1/image-to-image` and `blend` models.)
- Workflow tooling: V8.1 ships with a Prompt Shortener and an updated `/describe` command, and its aesthetic has been re-tuned "in the spirit of V7" to preserve the look users prefer.
Run Youchuan V8.1 Text-to-Image
from $0.13/imageParameters
What you can set.
| Parameter | What it does | Options |
|---|---|---|
prompt | Natural-language description of the image to generate. Maximum 1024 characters (Youchuan command flags embedded in the prompt are not counted toward the limit). Each task returns 4 images. | default A serene mountain lake at sunrise, photorealistic |
sref | Optional URL of a style-reference image. Must be a publicly reachable https image URL. | |
aspect_ratio | Aspect ratio of the generated image. | 1:1 9:16 16:9 4:3 3:4 2:3 3:2 9:21 21:9 |
hd | Enable native 2K HD generation. Costs 1.5x. | default |
stylize | Controls how strongly the model's default aesthetic is applied (0-1000). | default |
chaos | Higher values produce more unusual and varied results (0-100). | default |
weird | Makes results quirky and unconventional (0-3000). | default |
quality | Controls image detail. 4 = higher detail at the same price (slower). v8.1 supports 1 or 4 only. | 1 4 |
seed | Use the same seed and prompt to get reproducible results. -1 = random. | default -1 |
Sample prompt
The prompt behind the sample.
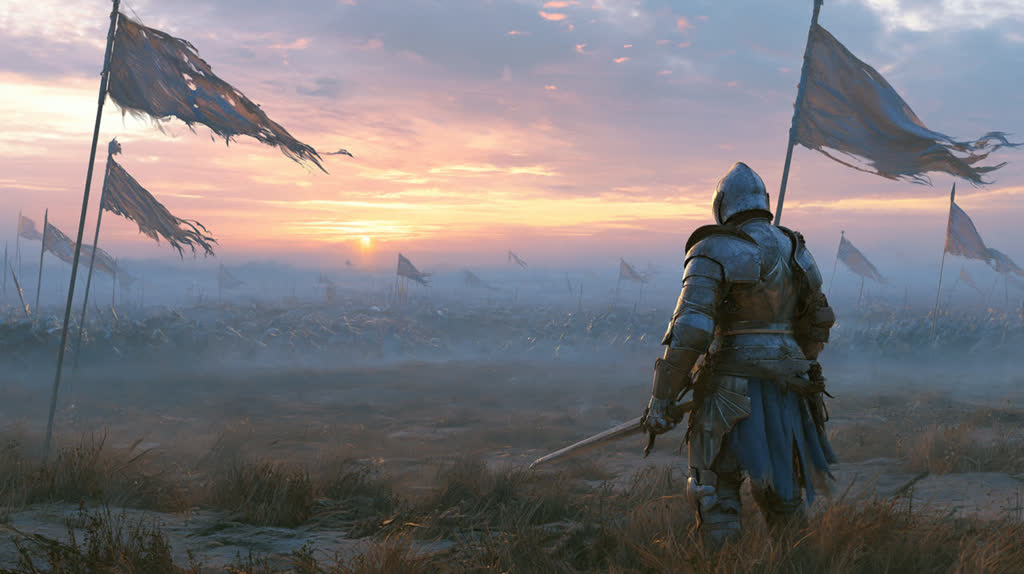
Medieval knight in shining steel armor, standing on a vast battlefield at sunrise, tattered banners waving in the wind, cinematic lighting, epic atmosphere, ultra detailed armor, realistic textures, volumetric fog, masterpiece, photorealistic,
aspect_ratio: 16:9hd: stylize: chaos: weird: quality: 1seed: -1enable_base64_output: FAQ
Short answers.
How much does Youchuan V8.1 Text-to-Image cost?
Pricing starts at $0.13 per image at the base resolution; higher resolutions and longer durations cost more. Usage is billed per request from your balance — no subscription.
Does Youchuan V8.1 Text-to-Image run uncensored here?
No. Midjourney applies its own content policy to this model regardless of where it is called from. For a route without an extra platform filter use Uncensored MiniMax H3; this page lists Youchuan V8.1 Text-to-Image for everything else it does well.
What does Youchuan V8.1 Text-to-Image take as input?
It is a text-to-image model. Youchuan V8.1 generates four images from a text prompt, with optional native 2K HD, a style reference, and aspect-ratio / stylize / chaos / weird controls.
How do I use it?
Enter an invite code to open Chat with the model loaded, or join the waitlist. We open seats in batches and track which models are requested most.
Related