
FLUX.2 Flex Text-to-image
FLUX.2 Flex is a professional text-to-image generation model specialized for typography, fine detail preservation, and production workflows requiring precise customization. It provides adjustable inference steps (1–50) and guidance scale (1.5–10) for fine-grained control, delivering high-quality output up to 4MP.
What it does
FLUX.2 Flex Text-to-image, in practice.
Developer: Black Forest Labs Model ID: black-forest-labs/flux-2-flex/text-to-image Release Date: February 23, 2026
- Superior typography — Reliable text rendering for complex typography, infographics, memes, UI mockups, and marketing materials with legible fine text.
- Adjustable inference parameters — Fine-grained control through configurable steps (1–50) and guidance scale (1.5–10) to balance quality, speed, and prompt adherence.
- High-resolution output up to 4MP — Flexible aspect ratios with a fundamentally improved VAE achieving 63.5% better learnability (gFID) and 84.1% better reconstruction quality (LPIPS) versus prior architectures.
- HEX color accuracy — Precise color matching using hex color codes for brand-accurate asset creation.
- Prompt expansion — Optional automatic prompt enrichment to improve output quality from short or simple prompts.
- Typography and text-heavy design — Infographics, magazine spreads, UI mockups, price tags, labels, and promotional materials requiring accurate text rendering.
Run FLUX.2 Flex Text-to-image
from $0.075/imageParameters
What you can set.
| Parameter | What it does | Options |
|---|---|---|
prompt | Text prompt for image generation. | |
enable_prompt_expansion | Whether to use prompt upsampling to enhance the prompt before generation. | default True |
size | Image dimensions in width*height format (e.g., 1024*1024, 1280*720), If not specified, the model will determine the optimal dimension. | default 1024*1024 |
guidance_scale | Guidance scale for image generation. High guidance scales improve prompt adherence at the cost of reduced realism. | default 5 |
num_inference_steps | Number of steps for image generation. Higher steps lead to more detailed and realistic images. | default 50 |
output_format | The format of the output image. | jpeg png |
safety_tolerance | Tolerance level for input and output moderation. Between 0 and 5, 0 being most strict, 5 being least strict. | default 2 |
seed | Random seed for reproducibility. Use -1 for a random seed. | default -1 |
Sample prompt
The prompt behind the sample.
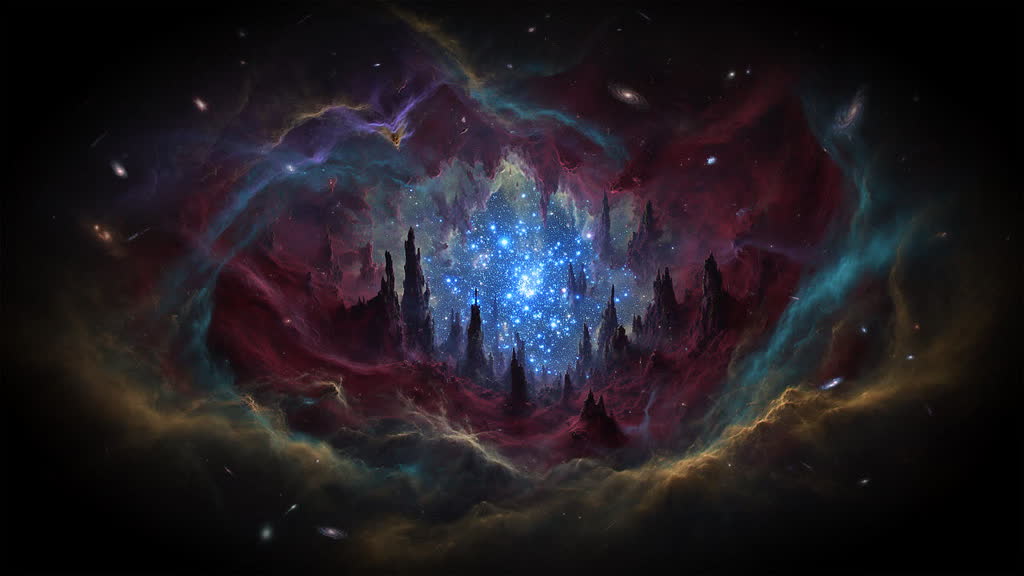
A wide-angle astrophotography shot capturing a vast, vibrant emission nebula. Intense colors of cosmic gas and dust: deep crimson, indigo, radiant cyan, and shimmering gold swirling together. In the dense center, thousands of young, brilliant blue stars are forming, surrounded by pillars of dark dust. Several remote galaxies are visible in the deep background. Shot on Hasselblad H6D, capturing every minute detail of the dust clouds. Cinematic lighting, breathtakingly vast.
enable_prompt_expansion: Truesize: 1280*720guidance_scale: 5num_inference_steps: 50output_format: jpegsafety_tolerance: 2seed: -1enable_base64_output: FAQ
Short answers.
How much does FLUX.2 Flex Text-to-image cost?
Pricing starts at $0.075 per image at the base resolution; higher resolutions and longer durations cost more. Usage is billed per request from your balance — no subscription.
Does FLUX.2 Flex Text-to-image run uncensored here?
No. Black Forest Labs applies its own content policy to this model regardless of where it is called from. For a route without an extra platform filter use Uncensored MiniMax H3; this page lists FLUX.2 Flex Text-to-image for everything else it does well.
What does FLUX.2 Flex Text-to-image take as input?
It is a text-to-image model. FLUX.2 Flex is a professional text-to-image generation model specialized for typography, fine detail preservation, and production workflows requiring precise customization. It provides adjustable inference steps (1–50) and guidance scale (1.5–10) for fine-grai
How do I use it?
Enter an invite code to open Chat with the model loaded, or join the waitlist. We open seats in batches and track which models are requested most.
Related