
Qwen Image 3.0 Text-to-Image
Generates images from a text prompt at resolutions up to 2048×2048, with automatic prompt rewriting and prompt-guided resolution selection, building on Qwen strength in complex text rendering and precise prompt adherence
What it does
Qwen Image 3.0 Text-to-Image, in practice.
Run Qwen Image 3.0 Text-to-Image
from $0.045/imageParameters
What you can set.
| Parameter | What it does | Options |
|---|---|---|
prompt | The text prompt describing the image to generate. | |
size | Output resolution as width*height (e.g. 2048*2048). Omit to let the model pick a resolution automatically from the prompt. Valid range: 512*512–2048*2048. | |
n | Number of images to generate. | default 1 |
negative_prompt | Describes content that should NOT appear in the generated image. | |
seed | Seed for reproducible generation, range [0, 2147483647]. Omit for a random seed. | |
prompt_extend | Enable intelligent prompt rewriting for richer results. | default True |
prompt_extend_mode | Prompt rewriting strategy. 'direct' (DPE) rewrites in a single pass; 'agent' (APE) uses an agentic rewrite pipeline. | direct agent |
Sample prompt
The prompt behind the sample.
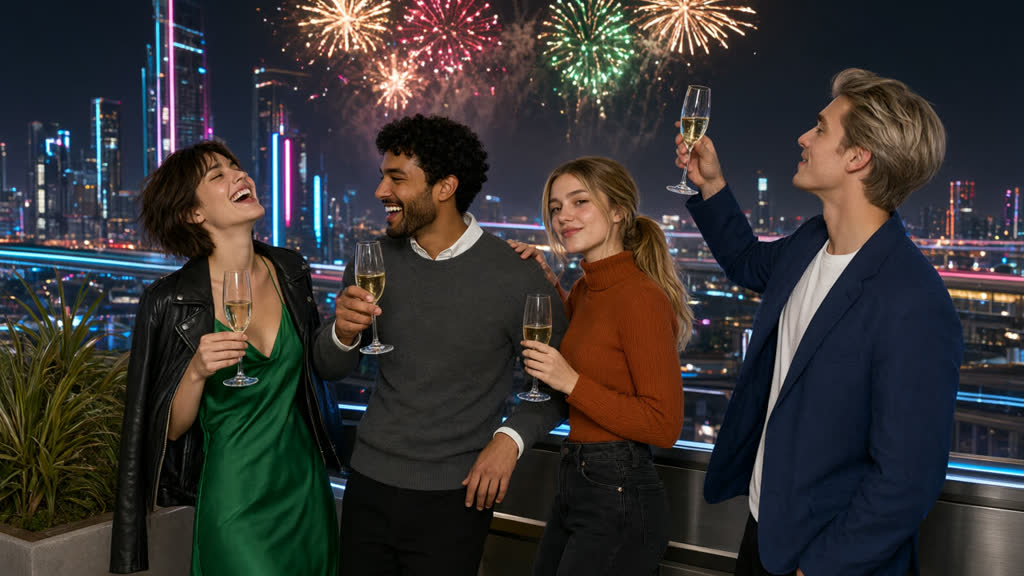
A group of close friends celebrating on a rooftop overlooking a futuristic city, colorful fireworks illuminating the night sky, champagne glasses raised, laughter frozen in time, cinematic lighting, emotional storytelling, shallow depth of field, anamorphic lens, ultra realistic, 8K
size: 1280*720n: 1prompt_extend: Trueprompt_extend_mode: directwatermark: FAQ
Short answers.
How much does Qwen Image 3.0 Text-to-Image cost?
Pricing starts at $0.045 per image at the base resolution; higher resolutions and longer durations cost more. Usage is billed per request from your balance — no subscription.
Does Qwen Image 3.0 Text-to-Image run uncensored here?
No. Qwen applies its own content policy to this model regardless of where it is called from. For a route without an extra platform filter use Uncensored MiniMax H3; this page lists Qwen Image 3.0 Text-to-Image for everything else it does well.
What does Qwen Image 3.0 Text-to-Image take as input?
It is a text-to-image model. Generates images from a text prompt at resolutions up to 2048×2048, with automatic prompt rewriting and prompt-guided resolution selection, building on Qwen strength in complex text rendering and precise prompt adherence
How do I use it?
Enter an invite code to open Chat with the model loaded, or join the waitlist. We open seats in batches and track which models are requested most.
Related