
Seedream v4.5
ByteDance latest image generation model achieving all-round improvements. Excels at typography, poster design, and brand visual creation with superior prompt adherence.
What it does
Seedream v4.5, in practice.
Seedream 4.5 is a state-of-the-art, multimodal generative model engineered for scalability, efficiency, and professional-grade output. As an advanced version of Seedream 4.0, it is built upon a unified framework that seamlessly integrates text-to-image synthesis, sophisticated image editing, and complex multi-image composition. The model's primary design goal is to deliver professional visual creatives with exceptional consistency and fidelity. This is achieved through a significant scaling of the model architecture and training data, which enhances its ability to preserve reference details, render dense text and typography accurately, and understand nuanced user instructions.
- Unified Multimodal Framework: Integrates text-to-image (T2I), single-image editing, and multi-image composition into a single, cohesive model, allowing for diverse and flexible creative workflows.
- High-Fidelity & High-Resolution Generation: Capable of generating native high-resolution images (up to 4K), capturing fine details, realistic textures, and accurate lighting for professional use cases.
- Advanced Image Editing: Excels at preserving the core structure, lighting, and color tone of reference images while applying precise edits based on natural language instructions.
- Enhanced Multi-Image Composition: Accurately identifies and blends main subjects from multiple reference images, enabling complex creative compositions and style fusions.
- Superior Typography and Text Rendering: Features significantly improved capabilities for rendering clear, legible, and contextually integrated text within images.
- Efficient and Scalable Architecture: Built on a highly efficient Diffusion Transformer (DiT) and a powerful Variational Autoencoder (VAE), enabling fast inference and effective scalability.
Run Seedream v4.5
from $0.054/imageParameters
What you can set.
| Parameter | What it does | Options |
|---|---|---|
prompt | The positive prompt for the generation. | |
size | Output image size in 'WIDTH*HEIGHT' pixels. 16 preset resolutions at 2K and 4K tiers. | 2048*2048 2304*1728 1728*2304 2848*1600 1600*2848 2496*1664 1664*2496 3136*1344 4096*4096 4704*3520 3520*4704 5504*3040 |
Sample prompt
The prompt behind the sample.
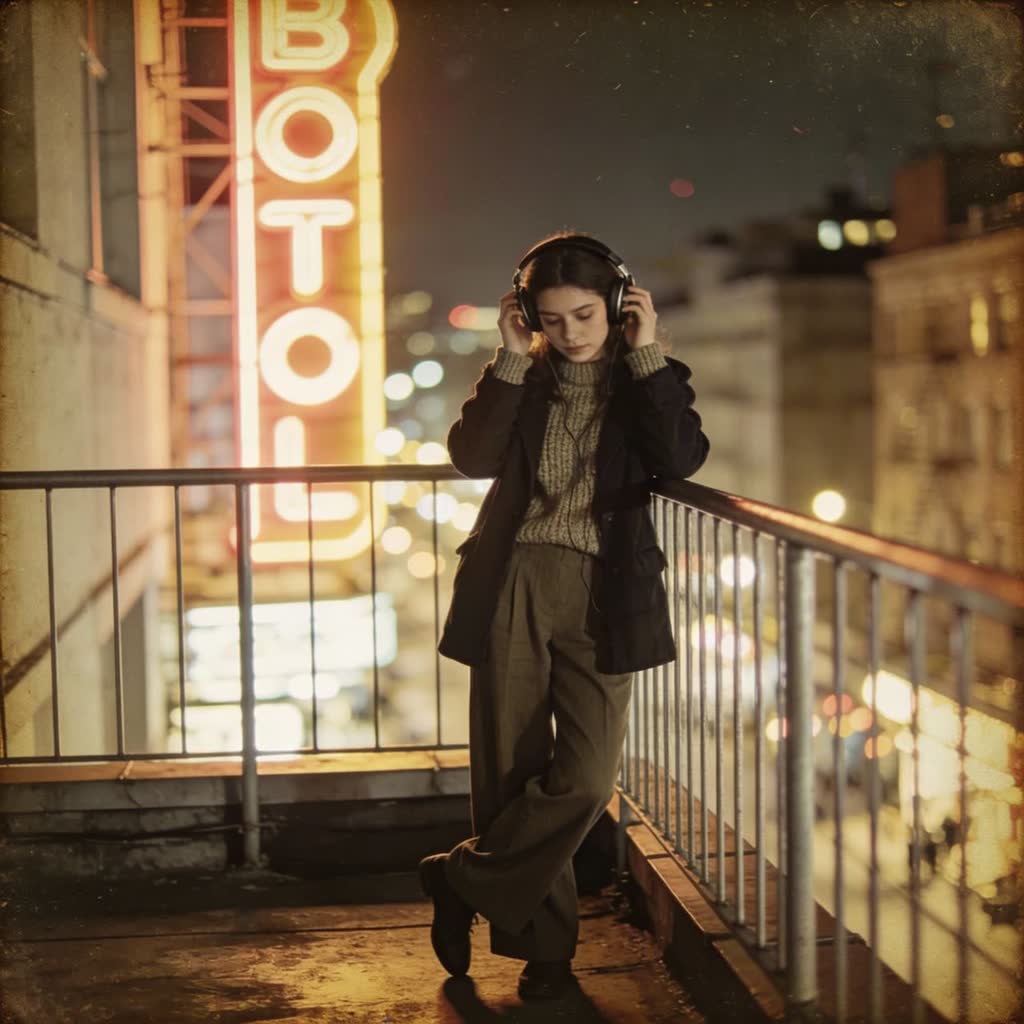
Nighttime urban photoshoot: A young woman stands on a rooftop terrace, leaning against a metal railing while adjusting her headphones. One foot crossed casually, relaxed yet focused. She wears a dark coat over a knit sweater and wide-leg trousers. City neon lights glow behind her with soft bokeh reflections, cinematic framing, vintage film photography style.
enable_base64_output: size: 2048*2048FAQ
Short answers.
How much does Seedream v4.5 cost?
Pricing starts at $0.054 per image at the base resolution; higher resolutions and longer durations cost more. Usage is billed per request from your balance — no subscription.
Does Seedream v4.5 run uncensored here?
No. ByteDance applies its own content policy to this model regardless of where it is called from. For a route without an extra platform filter use Uncensored MiniMax H3; this page lists Seedream v4.5 for everything else it does well.
What does Seedream v4.5 take as input?
It is a text-to-image model. ByteDance latest image generation model achieving all-round improvements. Excels at typography, poster design, and brand visual creation with superior prompt adherence.
How do I use it?
Enter an invite code to open Chat with the model loaded, or join the waitlist. We open seats in batches and track which models are requested most.
Related