
Seedream v4.7 Sequential
ByteDance Seedream 4.7 with batch generation support. Generate a set of coherent images in a single request.
What it does
Seedream v4.7 Sequential, in practice.
Seedream 4.7 Sequential is the group-generation variant of ByteDance Seed's Seedream 4.7 image model, exposed as the API model identifier bytedance/seedream-v4.7/sequential. Instead of returning a single image, it produces a set of images that belong together — a season cycle, a storyboard, a product line, a brand system — from one prompt in one request. The variant shares the base model's generation pipeline and adds sequential decoding, in which each image in the set is produced with awareness of the others. Style, palette, lighting, and viewpoint stay consistent across the group without the prompt engineering normally required to force consistency across independent calls. Results stream
- Coherent Image Sets: Generates up to 14 related images per request, holding style, color treatment, and composition logic constant across the set.
- Model-Determined Count: The model decides how many images the prompt actually calls for, up to the requested ceiling — a prompt describing four seasons yields four panels without the count being enforced manually.
- Progressive Delivery: Each image is returned as soon as it is generated rather than after the full set completes, keeping long multi-image requests responsive.
- Per-Image Fault Isolation: If one image in a set fails content moderation, the remaining images still return; only an internal service error halts the batch.
- Full Resolution Range: Every image in the set may be generated at 1K, 2K, or 4K, or at explicit `WIDTH*HEIGHT` dimensions.
- Shared Quality Baseline: Inherits Seedream 4.7's improvements in image quality, aesthetics, and instruction following, applied uniformly across the group.
Run Seedream v4.7 Sequential
from $0.045/imageParameters
What you can set.
| Parameter | What it does | Options |
|---|---|---|
num_images | The maximum number of images to generate. The number of reference images plus the number of generated images must not exceed 15 - if the total is exceeded the model silently generates fewer images than requested. This value must align with | default 1 |
prompt | The positive prompt for the generation. | |
prompt_expansion_mode | Prompt expansion mode. 'standard' favours output quality; 'fast' lowers latency with a possible small quality trade-off. | standard fast |
size | Output image size in 'WIDTH*HEIGHT' pixels. Presets cover the 1K, 2K and 4K tiers. Total pixels (width x height) must be between 921,600 and 16,777,216; aspect ratio must be between 1:16 and 16:1. | 2048*2048 2304*1728 1728*2304 2848*1600 1600*2848 2496*1664 1664*2496 3136*1344 4096*4096 4704*3520 3520*4704 5504*3040 |
Sample prompt
The prompt behind the sample.
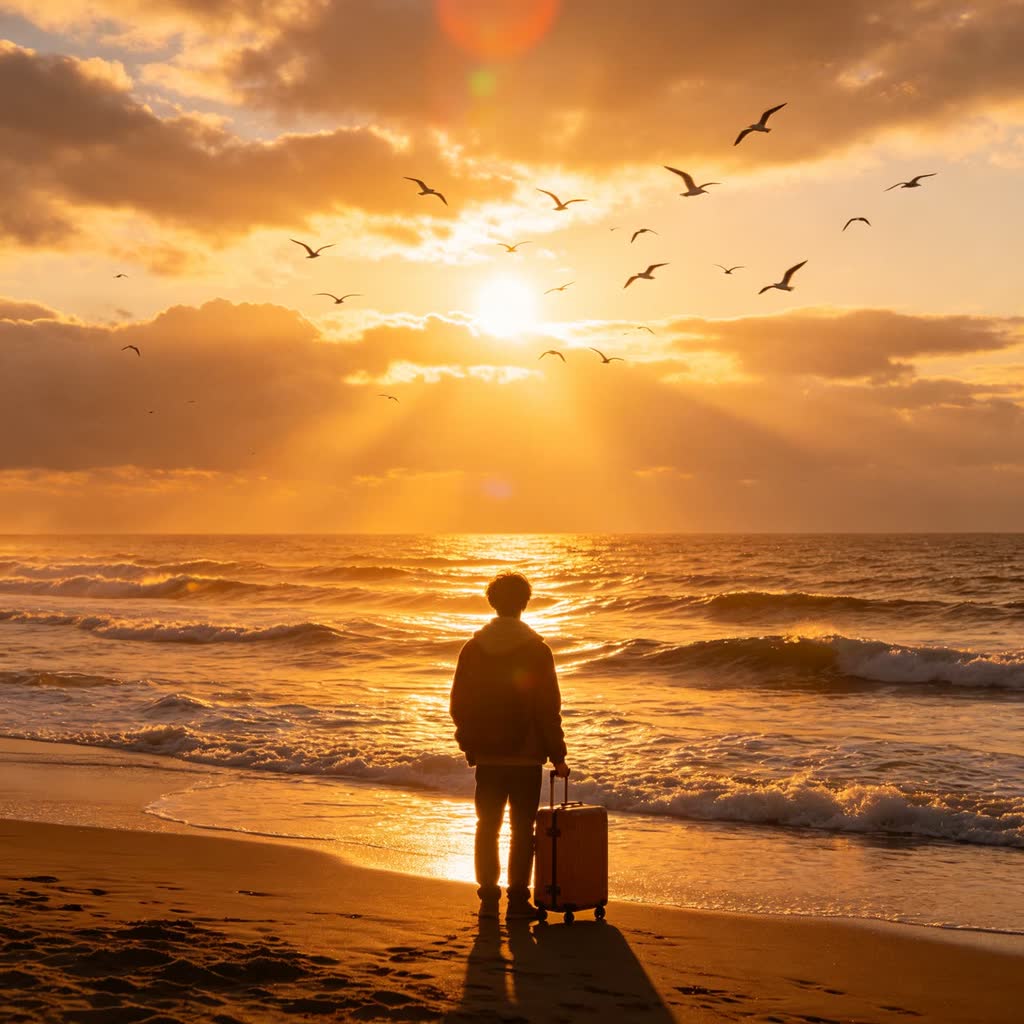
A young traveler standing at the edge of a vast ocean at sunrise, holding a small suitcase beside him, golden waves stretching toward the horizon, birds flying across the sky, sunlight breaking through the clouds behind him, strong feeling of hope, freedom and new beginnings, epic cinematic composition, emotional storytelling, anamorphic lens flare, subtle 35mm film grain
enable_base64_output: num_images: 1prompt_expansion_mode: standardsize: 1280*720FAQ
Short answers.
How much does Seedream v4.7 Sequential cost?
Pricing starts at $0.045 per image at the base resolution; higher resolutions and longer durations cost more. Usage is billed per request from your balance — no subscription.
Does Seedream v4.7 Sequential run uncensored here?
No. ByteDance applies its own content policy to this model regardless of where it is called from. For a route without an extra platform filter use Uncensored MiniMax H3; this page lists Seedream v4.7 Sequential for everything else it does well.
What does Seedream v4.7 Sequential take as input?
It is a text-to-image model. ByteDance Seedream 4.7 with batch generation support. Generate a set of coherent images in a single request.
How do I use it?
Enter an invite code to open Chat with the model loaded, or join the waitlist. We open seats in batches and track which models are requested most.
Related