
MAI-Image-2.5-Pro Text-to-image
Microsoft AI's highest-fidelity text-to-image model, generating photorealistic, visually dense scenes from natural language with strong object and character consistency and accurate in-image text.
What it does
MAI-Image-2.5-Pro Text-to-image, in practice.
MAI-Image-2.5-Pro is Microsoft AI's highest-fidelity image model to date — a text-to-image generation model built for work where quality is the top priority. It uses a diffusion-based generative approach that progressively refines the image, producing strong alignment between the input text and the generated output. Compared with the standard MAI-Image-2.5, the Pro tier is tuned for robust object consistency, stronger visual reasoning, and deeper world knowledge, which makes it especially reliable on visually dense, multi-object scenes and on prompts that leave details to be inferred. Released in public preview on July 23, 2026 (model version 2026-06-19), it is the premium tier of the MAI-Im
- Object consistency across complex scenes — Objects retain the same identity, materials, proportions, markings, and orientation throughout a visually dense composition.
- Character consistency across views and moments — A person or character remains recognizably the same across poses, camera angles, expressions, clothing, and lighting conditions.
- Material and physical-property accuracy — Materials look and behave according to their real-world properties, including reflection, translucency, weight, texture, and deformation.
- Spatial and geometric reasoning — Objects are placed coherently in three-dimensional space, with credible scale, perspective, occlusion, and structural relationships.
- Photorealistic image synthesis — Realistic imagery with consistent visual structure, natural lighting, accurate skin tones, depth, and texture.
- High-fidelity portraits — Expressive, natural-looking portraits with accurate facial structure, lighting, and skin texture.
Run MAI-Image-2.5-Pro Text-to-image
from $0.18/imageParameters
What you can set.
| Parameter | What it does | Options |
|---|---|---|
prompt | Text prompt describing the image to generate. Maximum context length: 32,000 tokens. | |
size | Image dimensions in width*height format (e.g., 1024*1024, 1280*720). Minimum 768. The product of width × height must not exceed 1,048,576. | default 1024*1024 |
Sample prompt
The prompt behind the sample.
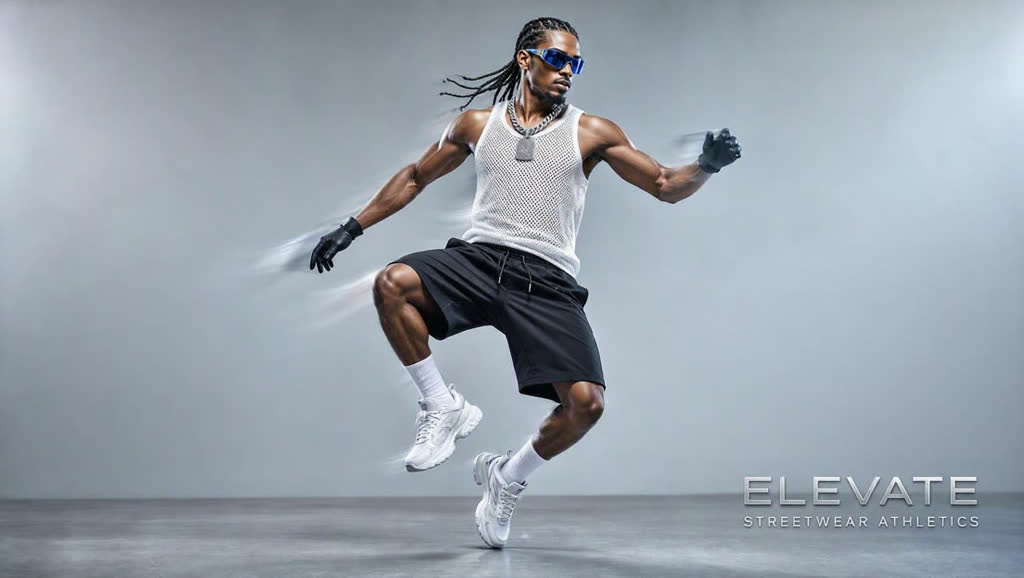
A stylish male streetwear model captured in a dynamic mid-air dance pose, one knee lifted high, body slightly twisted, arms extended with powerful movement, wearing a white mesh tank top, oversized black athletic shorts, white crew socks, white sneakers, black gloves, futuristic blue sunglasses and a silver chain necklace. Athletic physique, braided hair, confident and energetic attitude. Minimalist cool-gray studio background, soft diffused lighting, subtle shadows, clean editorial composition. High-end sportswear campaign, contemporary street fashion, cinematic fashion photography, dynamic c
size: 1360*768enable_base64_output: enable_sync_mode: FAQ
Short answers.
How much does MAI-Image-2.5-Pro Text-to-image cost?
Pricing starts at $0.18 per image at the base resolution; higher resolutions and longer durations cost more. Usage is billed per request from your balance — no subscription.
Does MAI-Image-2.5-Pro Text-to-image run uncensored here?
No. Microsoft applies its own content policy to this model regardless of where it is called from. For a route without an extra platform filter use Uncensored MiniMax H3; this page lists MAI-Image-2.5-Pro Text-to-image for everything else it does well.
What does MAI-Image-2.5-Pro Text-to-image take as input?
It is a text-to-image model. Microsoft AI's highest-fidelity text-to-image model, generating photorealistic, visually dense scenes from natural language with strong object and character consistency and accurate in-image text.
How do I use it?
Enter an invite code to open Chat with the model loaded, or join the waitlist. We open seats in batches and track which models are requested most.
Related