
Seedream v4.7 Text-to-Image
ByteDance Seedream 4.7 image generation model. Balanced gains in image quality, aesthetics and instruction following, at the efficiency and cost profile of the 4.0 generation.
What it does
Seedream v4.7 Text-to-Image, in practice.
Seedream 4.7 is ByteDance Seed's latest image generation and editing model, positioned as the balanced member of the Seedream family — tuned so that visual quality, editing fidelity, throughput, and cost land in the same place rather than trading against each other. This README covers the following API model identifiers: Relative to Seedream 4.5 and Seedream 5.0 Lite, version 4.7 delivers a more even improvement across image quality, aesthetic judgment, instruction response, and overall image-to-image experience. Its distinguishing characteristic is efficiency: ByteDance positions its performance and cost profile as on par with the 4.0/4.2 generation while measurably ahead of 4.5, which make
- Higher Image Quality and Aesthetics: In both text-to-image and image-to-image scenarios, outputs are cleaner and more natural, with stronger overall aesthetic composition than the preceding generation.
- Edit-Local Instruction Following: The model executes editing instructions more precisely while holding the source image's key information, subject consistency, and local structure stable — the combination that determines whether an edit is usable without manual repair.
- Multi-Reference Image Input: Accepts multiple reference images per request, as URLs or Base64, and reasons across them jointly for subject transfer, style grafting, and cross-image composition.
- Sequential Group Generation: The `/sequential` and `/edit-sequential` variants produce up to 15 thematically coherent images in a single call, holding style, palette, and viewpoint consistent across the set — suited to seasonal series, storyboards, and brand design systems.
- Native 4K Output: Generates up to 4096×4096 natively, alongside 1K and 2K tiers, with fine detail and texture preserved rather than upscaled after the fact.
- Flexible Sizing: Output size is specified either by resolution keyword (`1K`, `2K`, `4K`) or by explicit `WIDTH*HEIGHT` dimensions across a wide range of aspect ratios. In keyword mode the model selects an aspect ratio appropriate to the prompt, so a cinematic prompt returns a wide frame and a scene prompt returns a balanced one.
Run Seedream v4.7 Text-to-Image
from $0.045/imageParameters
What you can set.
| Parameter | What it does | Options |
|---|---|---|
prompt | The positive prompt for the generation. | |
prompt_expansion_mode | Prompt expansion mode. 'standard' favours output quality; 'fast' lowers latency with a possible small quality trade-off. | standard fast |
size | Output image size in 'WIDTH*HEIGHT' pixels. Presets cover the 1K, 2K and 4K tiers. Total pixels (width x height) must be between 921,600 and 16,777,216; aspect ratio must be between 1:16 and 16:1. | 2048*2048 2304*1728 1728*2304 2848*1600 1600*2848 2496*1664 1664*2496 3136*1344 4096*4096 4704*3520 3520*4704 5504*3040 |
Sample prompt
The prompt behind the sample.
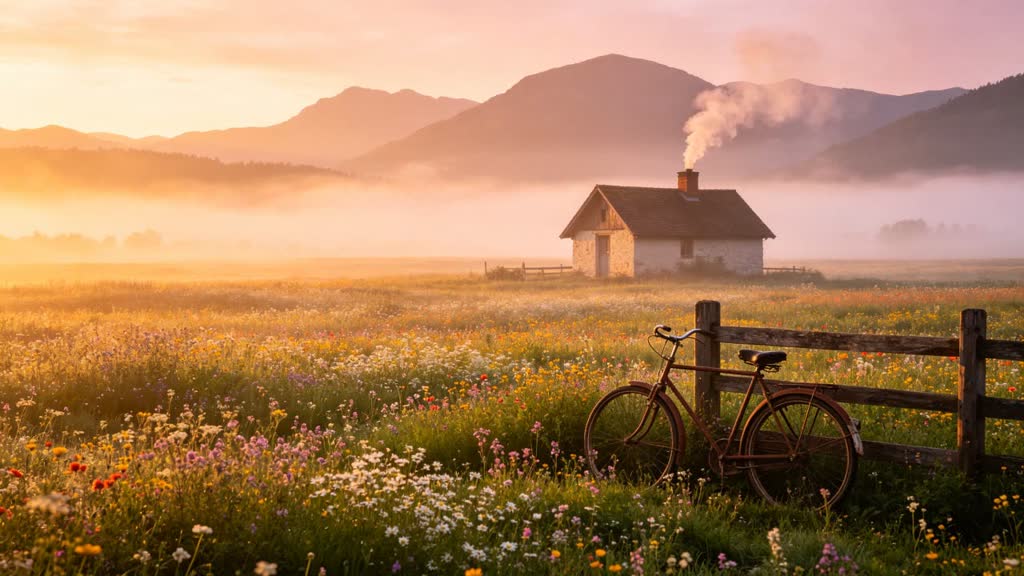
A tiny cottage surrounded by an endless field of wildflowers during sunrise, an old bicycle leaning against the wooden fence, smoke gently rising from the chimney, mountains hidden beneath morning mist, peaceful rural life, dreamy yet realistic, cinematic landscape photography, soft golden light, rich atmospheric depth
enable_base64_output: prompt_expansion_mode: standardsize: 1280*720FAQ
Short answers.
How much does Seedream v4.7 Text-to-Image cost?
Pricing starts at $0.045 per image at the base resolution; higher resolutions and longer durations cost more. Usage is billed per request from your balance — no subscription.
Does Seedream v4.7 Text-to-Image run uncensored here?
No. ByteDance applies its own content policy to this model regardless of where it is called from. For a route without an extra platform filter use Uncensored MiniMax H3; this page lists Seedream v4.7 Text-to-Image for everything else it does well.
What does Seedream v4.7 Text-to-Image take as input?
It is a text-to-image model. ByteDance Seedream 4.7 image generation model. Balanced gains in image quality, aesthetics and instruction following, at the efficiency and cost profile of the 4.0 generation.
How do I use it?
Enter an invite code to open Chat with the model loaded, or join the waitlist. We open seats in batches and track which models are requested most.
Related