
Nvidia Cosmos 3 Super Text-to-Image
Cosmos3 is a collection of Omnimodal world models capable of generating dynamic, high-quality video, image, audio, and action commands from combinations of text, image, video, and action trajectory inputs.
What it does
Nvidia Cosmos 3 Super Text-to-Image, in practice.
NVIDIA Cosmos 3 Super Text-to-Image is NVIDIA's flagship text-to-image model built on the Cosmos 3 architecture. Designed for high-fidelity physical world simulation, it delivers photorealistic images with strong prompt adherence, precise spatial reasoning, and support for negative prompting — making it well suited for both creative and technical generation tasks.
Run Nvidia Cosmos 3 Super Text-to-Image
from $0.066/imageParameters
What you can set.
| Parameter | What it does | Options |
|---|---|---|
prompt | The text prompt describing the image to generate. Maximum 2,500 characters. | |
negative_prompt | Text describing content to exclude from the generated image. | |
image_size | Output image resolution. Use a preset size or specify custom width and height via an ImageSize object. | default landscape_16_9 |
num_inference_steps | Number of denoising steps. Higher values improve quality but increase generation time. | default 28 |
guidance_scale | Classifier-free guidance scale. Higher values make the output follow the prompt more closely. | default 4.0 |
output_format | Output image format. | jpeg png |
seed | Random seed for reproducibility. Use the same seed and prompt to reproduce results. | |
enable_safety_checker | Enable or disable the safety checker. Disabling the safety checker may result in NSFW content. | default |
Sample prompt
The prompt behind the sample.
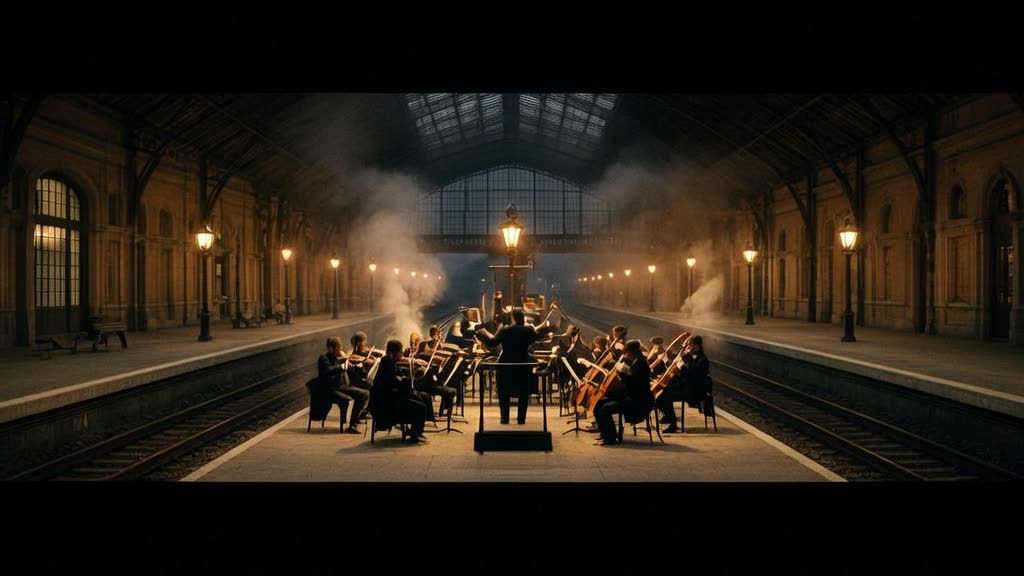
A symphony orchestra performing inside a grand European train station after the last train has departed. Empty platforms stretch into darkness while warm lantern light illuminates the musicians. Steam drifts through the air, creating a dreamlike cinematic atmosphere. Emotional storytelling, movie still, ultra realistic.
negative_prompt: image_size: landscape_16_9num_inference_steps: 28guidance_scale: 4output_format: jpegFAQ
Short answers.
How much does Nvidia Cosmos 3 Super Text-to-Image cost?
Pricing starts at $0.066 per image at the base resolution; higher resolutions and longer durations cost more. Usage is billed per request from your balance — no subscription.
Does Nvidia Cosmos 3 Super Text-to-Image run uncensored here?
No. Community applies its own content policy to this model regardless of where it is called from. For a route without an extra platform filter use Uncensored MiniMax H3; this page lists Nvidia Cosmos 3 Super Text-to-Image for everything else it does well.
What does Nvidia Cosmos 3 Super Text-to-Image take as input?
It is a text-to-image model. Cosmos3 is a collection of Omnimodal world models capable of generating dynamic, high-quality video, image, audio, and action commands from combinations of text, image, video, and action trajectory inputs.
How do I use it?
Enter an invite code to open Chat with the model loaded, or join the waitlist. We open seats in batches and track which models are requested most.
Related